概述
我最近在我的一个项目中遇到了垃圾回收问题。大量对象被重复分配,并导致 GC 的巨大工作量。使用 sync.Pool,我能够减少分配和 GC 工作负载。
什么是 sync.Pool?
Go 1.3 版本的亮点之一是同步池。它是 sync 包下的一个组件,用于创建自我管理的临时检索对象池。
为什么要使用 sync.Pool?
我们希望尽可能减少 GC 开销。频繁的内存分配和回收会给 GC 带来沉重的负担。sync.Poll 可以缓存暂时不使用的对象,并在下次需要时直接使用它们(无需重新分配)。这可能会减少 GC 工作负载并提高性能。
怎么使用 sync.Pool?
首先,您需要设置新函数。当池中没有缓存对象时将使用此函数。之后,您只需要使用 Get 和 Put 方法来检索和返回对象。另外,池在第一次使用后绝对不能复制。
由于 New 函数类型是 func() interface{},Get 方法返回一个 interface{}。为了得到具体对象,你需要做一个类型断言。1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24// A dummy struct
type Person struct {
Name string
}
// Initializing pool
var personPool = sync.Pool{
// New optionally specifies a function to generate
// a value when Get would otherwise return nil.
New: func() interface{} { return new(Person) },
}
// Main function
func main() {
// Get hold of an instance
newPerson := personPool.Get().(*Person)
// Defer release function
// After that the same instance is
// reusable by another routine
defer personPool.Put(newPerson)
// Using the instance
newPerson.Name = "Jack"
}
基准测试
1 | type Person struct { |
测试结果:1
2
3
4BenchmarkWithoutPool
BenchmarkWithoutPool-8 160698 ns/op 80001 B/op 10000 allocs/op
BenchmarkWithPool
BenchmarkWithPool-8 191163 ns/op 0 B/op 0 allocs/op
权衡
生活中的一切都是一种权衡。池也有它的性能成本。使用 sync.Pool 比简单的初始化要慢得多。1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18func BenchmarkPool(b *testing.B) {
var p sync.Pool
b.RunParallel(func(pb *testing.PB) {
for pb.Next() {
p.Put(1)
p.Get()
}
})
}
func BenchmarkAllocation(b *testing.B) {
b.RunParallel(func(pb *testing.PB) {
for pb.Next() {
i := 0
i = i
}
})
}
压测结果:1
2
3
4BenchmarkPool
BenchmarkPool-8 283395016 4.40 ns/op
BenchmarkAllocation
BenchmarkAllocation-8 1000000000 0.344 ns/op
sync.Pool 是如何工作的?
sync.Pool 有两个对象容器: 本地池 (活动) 和受害者缓存 (存档)。
根据 sync/pool.go ,包 init 函数作为清理池的方法注册到运行时。此方法将由 GC 触发。1
2
3func init() {
runtime_registerPoolCleanup(poolCleanup)
}
当 GC 被触发时,受害者缓存中的对象将被收集,然后本地池中的对象将被移动到受害者缓存中。1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17func poolCleanup() {
// Drop victim caches from all pools.
for _, p := range oldPools {
p.victim = nil
p.victimSize = 0
}
// Move primary cache to victim cache.
for _, p := range allPools {
p.victim = p.local
p.victimSize = p.localSize
p.local = nil
p.localSize = 0
}
oldPools, allPools = allPools, nil
}
新对象被放入本地池中。调用 Put 方法也会将对象放入本地池中。调用 Get 方法将首先从受害者缓存中获取对象,如果受害者缓存为空,则对象将从本地池中获取。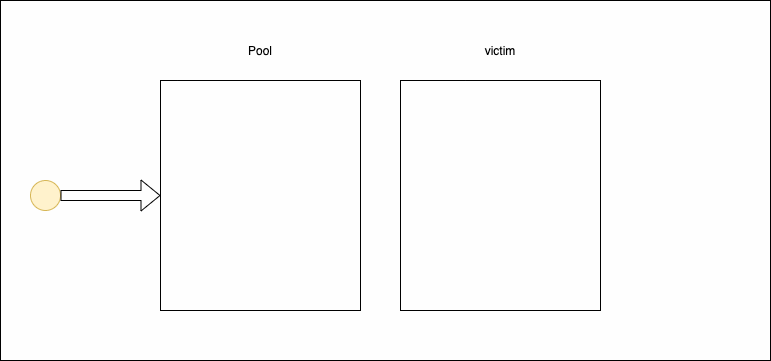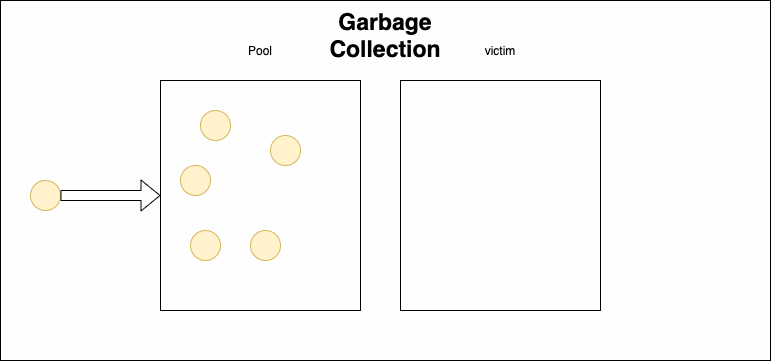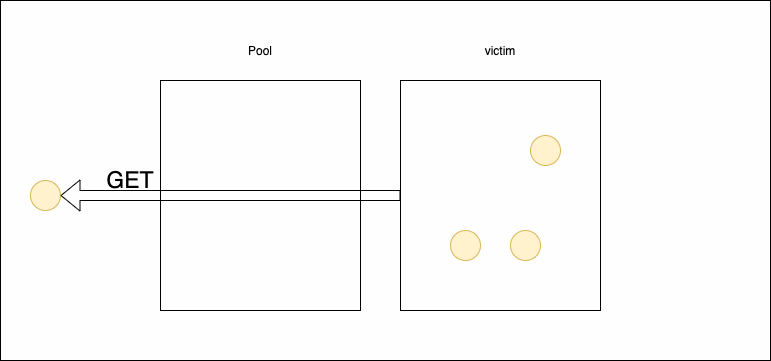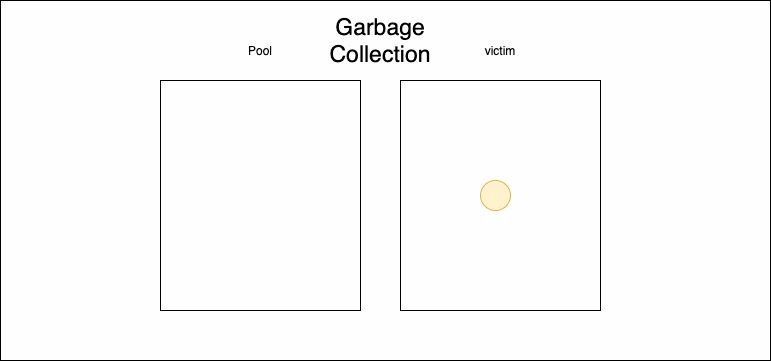
供你参考,Go 1.12 sync.pool 实现使用基于 mutex 的锁,用于来自多个 Goroutines 的线程安全操作。Go 1.13 引入了一个双链表作为共享池,它删除了 mutex 并改善了共享访问。
结论
当有一个昂贵的对象需要频繁创建时,使用 sync.Pool 是非常有益的。
译自:https://medium.com/swlh/go-the-idea-behind-sync-pool-32da5089df72